
GDPR & AI: Safe Local Hosting for LLMs

Across Europe, IT leaders are asked to prove AI's value before next quarter's budget cycle closes. Yet one misplaced prompt can expose customer records, attract fines of up to €20 million or 4 % of worldwide annual turnover (Art. 83 GDPR) and put AI projects on hold. The question is no longer if you'll adopt generative AI, but where you'll run it.
Where cloud-first LLMs conflict with the GDPR
Public-cloud AI platforms advertise EU availability zones, but key data still drifts beyond your control:
- Trans-atlantic spill-over. Support logs, model telemetry or security snapshots can be mirrored to U.S. teams. Under the US CLOUD Act, US providers can be required to hand over data wherever it is stored (18 U.S.C. § 2713). Since the European Commission's adequacy decision of 10 July 2023, personal data may be transferred to US companies certified under the EU-US Data Privacy Framework (European Commission).
- Unbounded retention. "Service-improvement" clauses can let providers store and retrain on user prompts.
- Shadow processors. Each plug-in widens the unknown sub-processor chain, complicating Article 28 assessments.
- Opaque audit data. Usage dashboards rarely include field-level logs, making Article 30 records or works-council reviews harder.
- Purpose & storage limits. Once a ticket excerpt hits a shared LLM, you lose deterministic control over its lifespan or reuse.
On its way from your network to the provider, a single prompt can end up in several places:
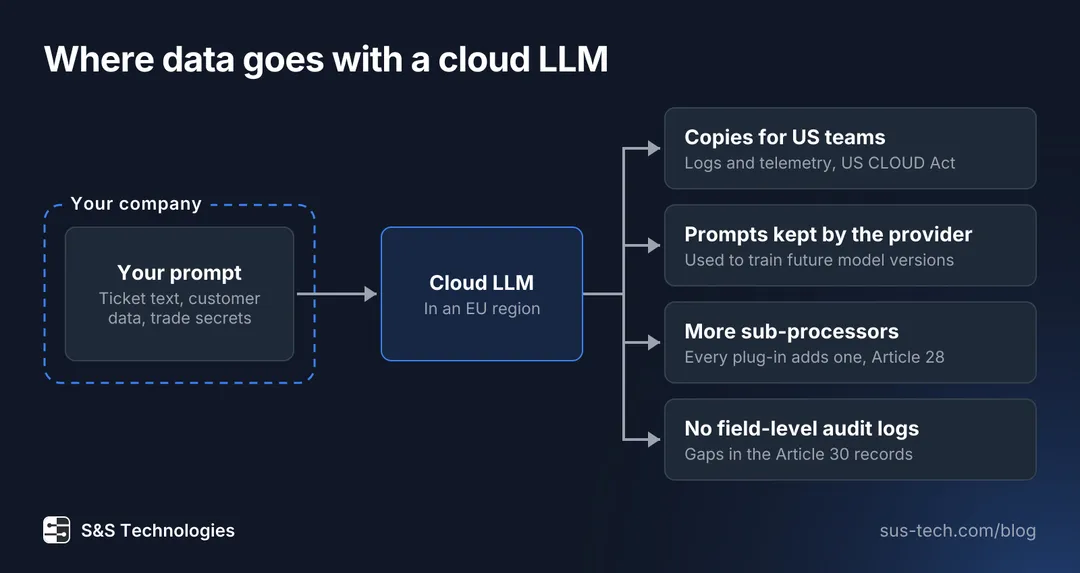
Even when the model runs in an EU region, the prompt has left your network. Logs and telemetry can be copied to US teams under the US CLOUD Act, prompts can be stored and used to train later model versions, every plug-in adds a sub-processor and the provider's dashboards lack the field-level logs your Article 30 records need.
The risk is real: in 2023 Samsung restricted the use of ChatGPT and similar tools after engineers had pasted internal source code into ChatGPT (TechCrunch). Once data sits on an external server, a company can hardly retrieve or delete it.
Take-away: A "GDPR-ready" badge does not equal full accountability when trade secrets and personal data are involved.
What local AI gives you beyond compliance
Hosting large language models inside EU data centres or your own racks delivers more than legal certainty:
- Data residency & sovereignty. No cross-border transfers, no Schrems II issues.
- Granular observability. Log every token, vector store query and file hand-off for complete audit trails.
- Custom fine-tuning. Adapt the model to your terminology and processes without sending training data to a third party.
- Lower latency. Requests do not travel to a cloud provider and back, so agents answer faster.
- Predictable economics. Hardware is a fixed cost; at high volumes it costs less than per-token pricing (see our cost comparison).
- Sustainable operations. Local workloads can tap existing heat-re-use or hydro-powered facilities, shrinking carbon footprints.
Local-first automation with governance
At S&S Technologies we combine open-source models with n8n, Matrix42, Jira and other service management software to build private, governed AI services:
- Local model instances. Each tenant runs its own LLMs with on-prem hardware or on data centers that are in the EU.
- Encrypted/Local vector stores. Retrieval-augmented generation (RAG) stays within your firewall; zero plain-text exports. Or you host the vector store yourself.
- Versioned pipelines. Every prompt, response and transform step is captured in n8n flows, which gives auditors a complete trail.
- Right-sized hardware. From a single RTX 4000 edge node to multi-GPU A100 clusters - we size the hardware to the workload and budget.
Want the technical deep dive? Check our guide Running LLMs Locally.
From data mapping to a running system
- Discovery & mapping. We audit data flows, classify personal vs. business-critical data and define impact targets.
- Reference architecture. A three-tier blueprint - ingress gateway, model layer, automation layer - matches your network zones.
- Deployment. Depends on your use case, but is usually done with kubernetes or docker for on-prem AI.
- Integration. Low-code n8n workflows listen to ERP or ITSM events, enrich context and invoke the LLM behind a policy gateway.
- Tuning & guard-rails. The models are fine-tuned; the policy engine enforces PII masking, rate limits and content filters.
- Monitoring & optimisation. We can surface token, latency and cost dashboards.
Put together, the reference architecture from step 2 looks like this:
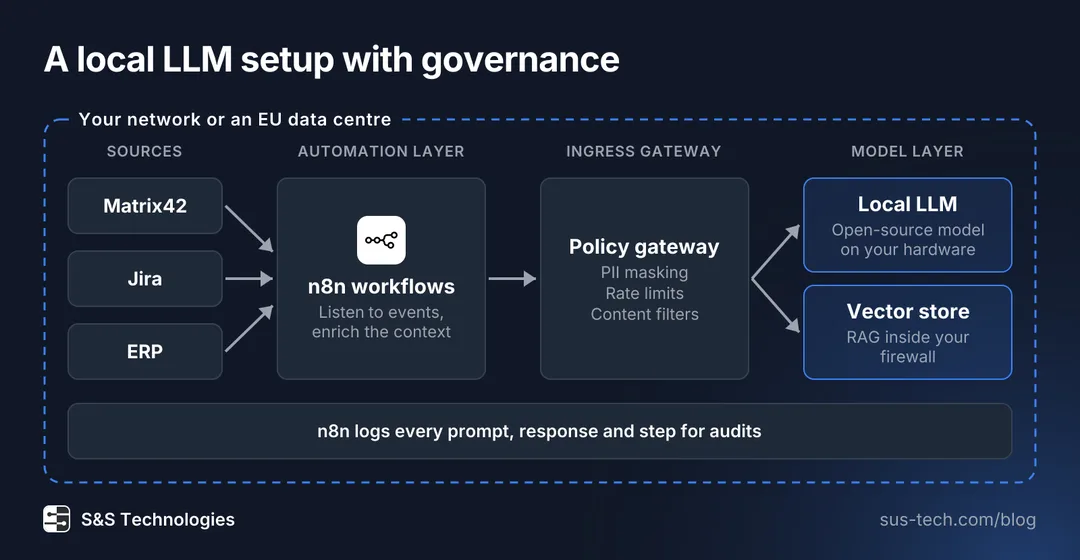
Matrix42, Jira or the ERP send their events to n8n, which enriches the context and calls the model only through the policy gateway. The gateway masks personal data and enforces rate limits and content filters. The local LLM and the vector store for RAG run on your own hardware or in an EU data centre. Every prompt, response and step is logged in n8n for audits.
Once the agent pipeline runs, a service desk can triage tickets faster - without ever sending a byte outside the EU or even better, its own network.
What specialised AI agents can deliver
- ITSM automation. Route incidents to the proper resolver group in seconds, summarise logs and draft status updates.
- ERP data enrichment. Match supplier names, reconcile VAT IDs and flag anomalies.
- Knowledge management. Turn resolved tickets into high-quality knowledge-base articles auto-tagged for search.
Each use case builds on the same pipeline with the same controls.
A five-question self-check
Run this 5-question self-check to gauge fit:
- Do we handle personal data that crosses EU borders today?
- Would our works council or auditors reject external AI logs?
- Are trade secrets embedded in support tickets or ERP notes?
- Do we need deterministic deletion and version control?
- Would automating triage, enrichment or reporting save your team noticeable effort?
If you answered yes to three or more, local AI is likely the better fit for you. Contact our team to start.
Automate. Optimize. Scale.