
Internal Knowledge Bases with RAG: Architecture, Tools and Maintenance

On a Monday morning, your service-desk agent drops a 300-page compliance PDF into an n8n workflow. Ten minutes later every employee can ask natural-language questions and get answers - each answer linked to the exact page it came from. Automate. Optimize. Scale.
Knowledge scattered across PDFs and wikis
Most organisations keep their know-how scattered across PDFs, wikis and SharePoint libraries. Keyword search surfaces dozens of near-matches and little context. The result?
- Slow ticket resolution and frustrated employees.
- Risk of out-of-date policies and non-compliant decisions.
- Manual curation that breaks the moment volumes grow.
Traditional enterprise search returns lists of documents, not direct answers with context.
Retrieval-augmented generation
Retrieval-Augmented Generation (RAG) gives a language model fresh, governed data. Instead of relying on the model's pre-training, RAG retrieves relevant document chunks from a vector store and passes them to the LLM at query time - complete with citations.
We build a pipeline for production use around RAG with n8n:
- Ingest files, URLs and databases.
- Chunk & embed content to vectors.
- Store embeddings in Milvus or pgvector.
- Query via chat UI, API or ITSM widget.
- Govern with RBAC, versioning and audit trails.
For data residency we deploy the LLM locally with Ollama, as outlined in our posts GDPR & AI: Safe Local Hosting for LLMs or How to Run LLMs Locally.
Building a RAG knowledge base step by step
A RAG knowledge base has two parts that share one vector store: indexing prepares new and changed documents, answering uses them for every question.
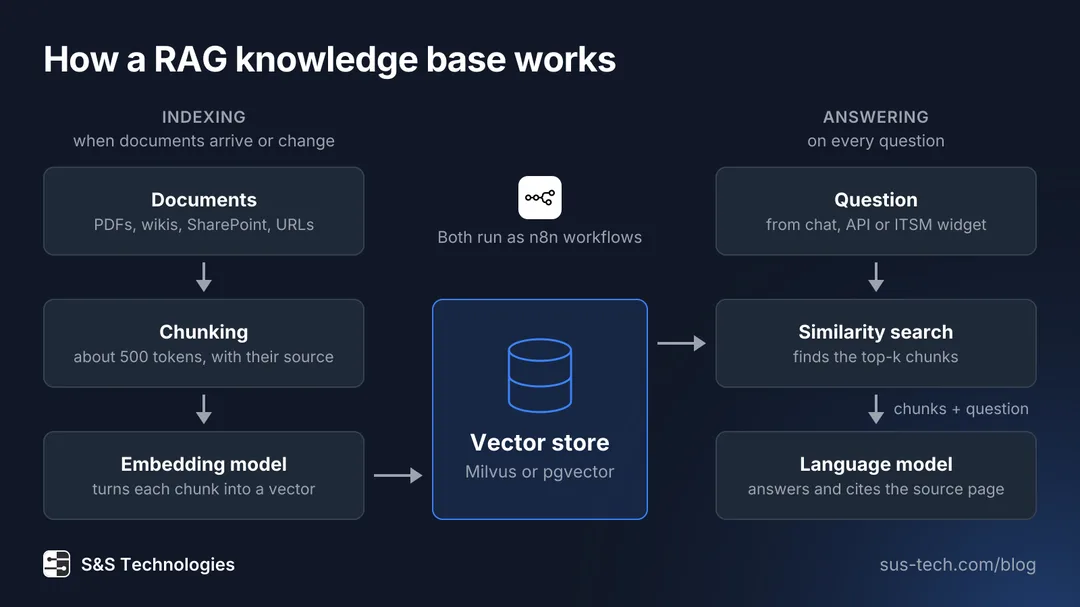
Indexing splits each document into chunks of about 500 tokens, turns them into vectors with an embedding model and stores them in Milvus or pgvector. For every question a similarity search finds the top-k chunks and the language model answers from them with a citation of the source page. Both parts run as n8n workflows. The five steps below go through them in detail.
1 - Ingestion & Chunking
An n8n trigger watches designated folders, S3 buckets or SharePoint. As new PDFs arrive, the workflow extracts text, splits it into semantically coherent chunks (e.g., 500 tokens) and tags each chunk with source metadata.
2 - Embeddings & Vector Store
Chunks pass to an embedding model - OpenAI, Instructor XL or an on-prem model - producing vectors. We write them into Milvus or pgvector alongside document IDs. The store updates incrementally, so weekly policy refreshes stay live without re-indexing everything.
3 - Retrieval + Generation
On each question the RAG layer performs a similarity search, selects the top-k chunks and sends them, plus the original query, to the LLM. The model crafts an answer in your corporate voice and appends inline citations so users trace facts back to the source page. No more "black-box" answers.
4 - Chat UX & Integration
A lightweight React widget - or a native panel inside your ITSM software - delivers the chat experience. Users can hover citations to open the PDF at the referenced page. All queries, retrieved chunks and responses are logged to satisfy auditors.
5 - Governance & Monitoring
Every artefact lives in Git-versioned n8n workflows. Scheduled process-mining jobs analyse usage patterns and flag outdated content.
What teams gain
What changes for the team:
- Faster ticket resolution, because answers are found in seconds instead of searched for.
- Fewer questions that need an expert, since the knowledge base answers the routine ones.
- Less time spent searching in knowledge-intensive workflows.
- Full audit trail of who saw what, when - crucial for ISO 27001 and GDPR.
Embedded in the help module of an ERP system, the RAG chat also shortens the onboarding of new agents: they ask the chat instead of a colleague.
How we set it up
Ready to put your own data to work? We work in three steps:
- 3-day discovery workshop: map knowledge sources, security and KPIs.
- Pilot build (2 - 4 weeks): ingest key docs, stand up vector store and chat UI.
- Measured rollout: baseline metrics, iterate, hand-over with playbooks.
Contact our team to schedule your session.