
Prompt Engineering Is Not Enough

Prompt engineering gave us the illusion of speed. With a single clever prompt, developers could spin up demos, assistants and language tasks in minutes. But when it comes to running mission-critical workflows across IT service desks, ERPs or finance ops, prompts alone just don't cut it. Enterprises need AI that's accurate, scalable and compliant. It's time to move beyond the prototype phase.
Where prompt engineering stops
At first glance, prompt engineering seems like a tech team's best friend. It's simple and low effort - just feed a large language model (LLM) the right prompt and you've got a working chatbot or an answer generator. But this approach quickly runs into walls in enterprise contexts:
- Lack of data access: Prompts rely solely on what the model was trained on. They can't fetch current, internal company data without risky and manual copy-pasting.
- Performance drift: Prompt outputs vary depending on subtle wording, often leading to brittle logic that fails under pressure.
- Security and compliance issues: Every API call to a public cloud LLM sends company data to a third party. GDPR Article 5(1)(f) requires the integrity and confidentiality of personal data. Transfers outside the EU fall under the rules of Chapter V.
- No contextual memory: Prompts don't maintain structured knowledge about tasks, roles or long-running conversations.
- Maintenance overhead: Tweaking behavior means rewriting prompts, testing permutations and chasing hallucinations.
In short, prompt engineering makes for impressive demos, but it's fragile in production.
Specialised AI agents instead of clever prompts
At S&S Technologies, we build specialised AI agents - self-contained, role-based systems that do more than rely on prompts. We enhance them with:
- Retrieval-Augmented Generation (RAG): Pulling up-to-date company data at runtime so the model has real context.
- Fine-tuned models: Using tools like LoRA and QLoRA to tailor language models to your company vocabulary, workflows and regulations.
- Governed automation: Combining low-code orchestration with permission controls, logging and performance dashboards.
This means your AI agents don't just respond - they act. They access databases, update ERP entries, tag tickets and escalate issues, all while complying with company-wide security policies. You get a production-ready automation layer that's dependable and adaptable.
Compared with a prompt on its own, the differences look like this:
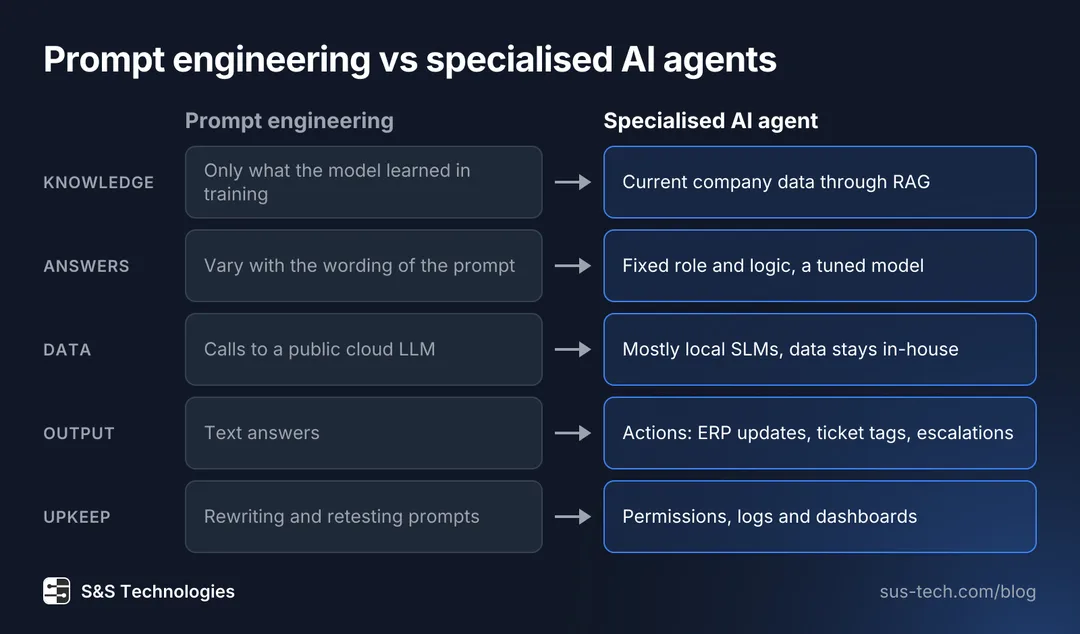
A prompt only knows what the model learned in training and its answers vary with the wording. A specialised agent pulls current company data through RAG and works in a fixed role with a tuned model. It runs mostly on local SLMs, acts in ERP and ticket systems and is controlled through permissions, logs and dashboards.
How the agents are built
Our architecture combines open tooling with deliberate design choices, built for company-wide use. Here's how it works:
- Agent design: We assign each agent a specific role (e.g. ticket triage bot, invoice classifier) and encode structured logic using n8n, a fair-code workflow orchestrator under the Sustainable Use License.
- Real-time context with RAG: Agents use RAG to retrieve knowledge from internal sources - like Confluence wikis, Jira tickets or SQL databases. This ensures responses are grounded and up-to-date.
- Domain tuning with LoRA/QLoRA: Based on data clustering, we fine-tune small language models (SLMs) locally using efficient techniques. For a quick overview see LLM Finetuning: LoRA and QLoRA.
- Model routing: A governance node decides in real time whether the local SLM is sufficient or if the agent should hand the request to a larger foundation model.
- Built-in compliance controls: Full audit logging, RBAC, human-in-the-loop and error tracking ensure every decision is transparent and safe.
Put together, the five parts form one flow:
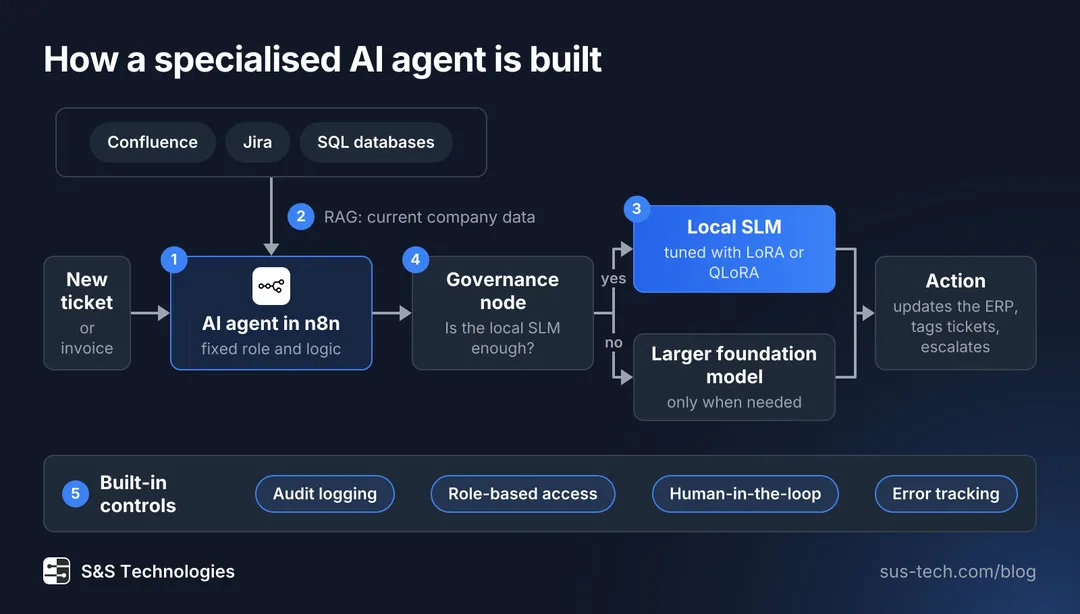
A new ticket or invoice reaches an agent in n8n with a fixed role. Through RAG it pulls current knowledge from Confluence, Jira or SQL databases. A governance node sends the request to a local SLM tuned with LoRA or QLoRA and only to a larger foundation model when the local model is not enough. The agent then acts, for example by updating the ERP, tagging a ticket or escalating it. Audit logging, role-based access, human-in-the-loop and error tracking cover every step.
The result: agents that are cost-effective, domain-relevant and privacy-compliant.
What agents deliver in production
Unlike unstructured prompt tools, these AI agents deliver real production outcomes:
- More accurate results thanks to context-aware inputs and fine-tuned decision graphs.
- Fewer manual steps, particularly in ERP and service desk automation.
- Shorter cycle times from ticket creation to resolution.
- Lower costs at high volumes by executing most agent calls on local SLMs instead of commercial LLM APIs.
- Data that stays in the EU or in-house, with the logs internal audits ask for.
The same points come up in our article Small Language Models (SLMs): Agentic AI for Your Workflow Automation, where we explain why most routine automation tasks can be handled locally and securely.
Moving from demo to production
Don't let a good demo keep you stuck in the pilot phase. Move beyond prompts:
- Identify AI-ready processes: tasks like ticket classification, ERP updates or HR triage are ideal.
- Run a targeted pilot: build one specialised AI agent using RAG and/or fine-tuning.
- Monitor business metrics: track cycle-time, escalation rate and manual rework.
- Scale with confidence: gradually expand coverage as governance, logging and routing rules ensure safe operation.
Contact our team at office@sus-tech.at to evaluate your use cases.
S&S Technologies - Automate. Optimize. Scale.