
Small Language Models (SLMs): Agentic AI for Your Workflow Automation

Did you know that specialised models under 10 billion parameters could reliably handle 40 to 70 % of the language model calls in the AI agents NVIDIA researchers studied? The NVIDIA Research paper "Small Language Models are the Future of Agentic AI" estimates about 60 % for MetaGPT, 40 % for Open Operator and 70 % for Cradle, three open-source agents. It also finds that serving a 7 billion-parameter model is 10 to 30 times cheaper in latency, energy and compute than serving one with 70 to 175 billion parameters. For companies wrestling with latency, sovereignty and budget constraints, the implications are significant.
Why cloud LLM calls get expensive
Many IT service desk operations rely on cloud LLM APIs for summarising tickets, enriching ERP records or generating knowledge-base answers. But heavy tokens mean heavy invoices while external calls can route sensitive data through data centres abroad - a risk for the confidentiality that GDPR Article 5(1)(f) requires. We unpacked these risks in our earlier post GDPR & AI: Safe Local Hosting for LLMs.
Add inconsistent round-trip latency and unpredictable rate limits and your automation suddenly looks more like a liability than an asset.
An automation stack that starts with small models
S&S Technologies solves the problem with a governed, SLM-first automation stack that keeps inference inside your firewall:
- n8n low-code workflows (learn more) orchestrate data flows across your software.
- Ollama-served small language models (SLMs) sit on a modest GPU - or even a high-core CPU - fine-tuned for your domain and compliance filters.
- A smart router node decides, in real time, whether the local SLM can handle the task or whether we should escalate to a larger LLM for edge-cases.
- Every prompt, response and model version is logged via our governance layer (RBAC, versioning, policy and dashboards).
Here is how a request moves through this stack:
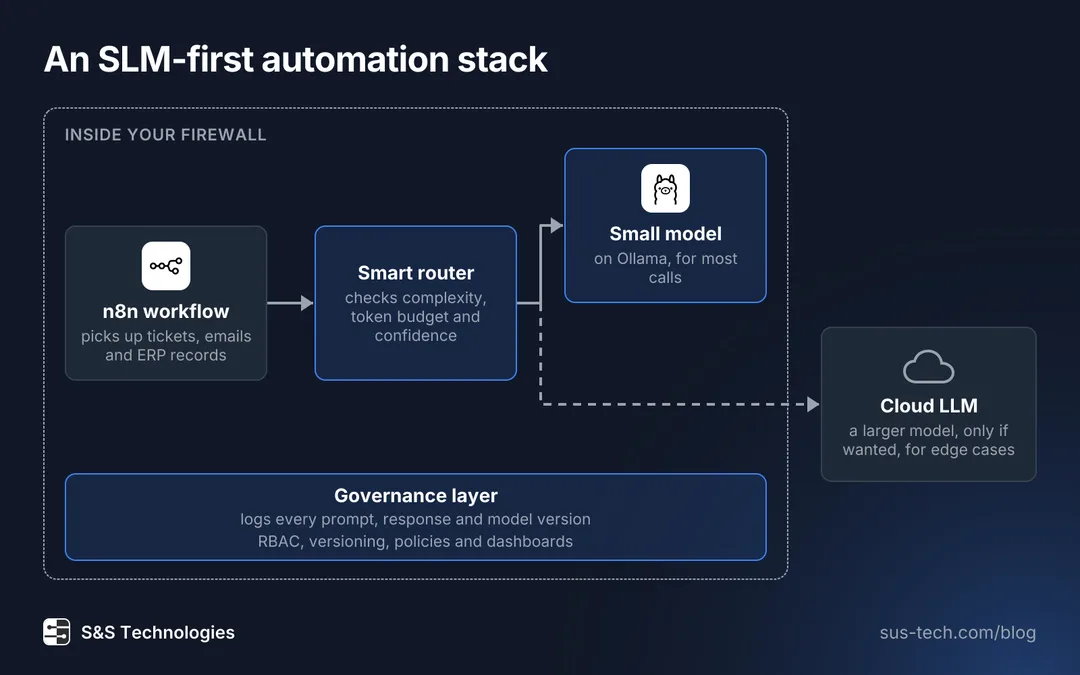
n8n picks up tickets, emails and ERP records and hands each task to the smart router. The router checks complexity, token budget and confidence. Most calls go to the small model on Ollama and never leave your network. Only edge cases go to a larger cloud LLM if you want that. The governance layer below logs every prompt, response and model version, whichever model answers.
Why SLM-first makes strategic sense
The NVIDIA paper frames the SLM advantage in three dimensions:
| Value pillar | What the paper demonstrates | Why it matters |
|---|---|---|
| Capability | Recent models under 10B parameters keep up with much larger ones in tool calling, instruction following and code generation. xLAM-2-8B even beats GPT-4o and Claude 3.5 in tool calling. | Service-desk macros, invoice parsing and status updates rarely need abstract reasoning. |
| Suitability | Smaller architectures are easier to fine-tune, debug and iterate. | Your DevOps team stays in control; no opaque "black-box" vendor updates. |
| Economy | Far lower cost and energy per token than large cloud models. | Budgets stretch further, letting you scale automation without CFO push-back. |
In short: SLMs let you start small, learn fast and stay compliant.
Moving agent tasks to small models
- Data capture & clustering: n8n collects historical tickets, emails and logs, then groups them into high-frequency intent clusters to reveal automation hotspots.
- Fine-tune or distill: Using parameter-efficient fine-tuning (PEFT) techniques such as LoRA and QLoRA, we adapt a 7B model to your vocabulary, redline words and compliance rules. For a step-by-step how-to, see Run Local LLMs with Ollama & n8n.
- Smart routing: A decision node checks task complexity, token budget and confidence scores; most calls stay local, the rest waterfall to a managed cloud LLM if needed.
- Governance & optimisation loop: Process-mining nodes benchmark cycle-time, accuracy and human-in-the-loop overrides, feeding metrics into a continuous-improvement backlog that runs every sprint.
The four steps repeat with every round:
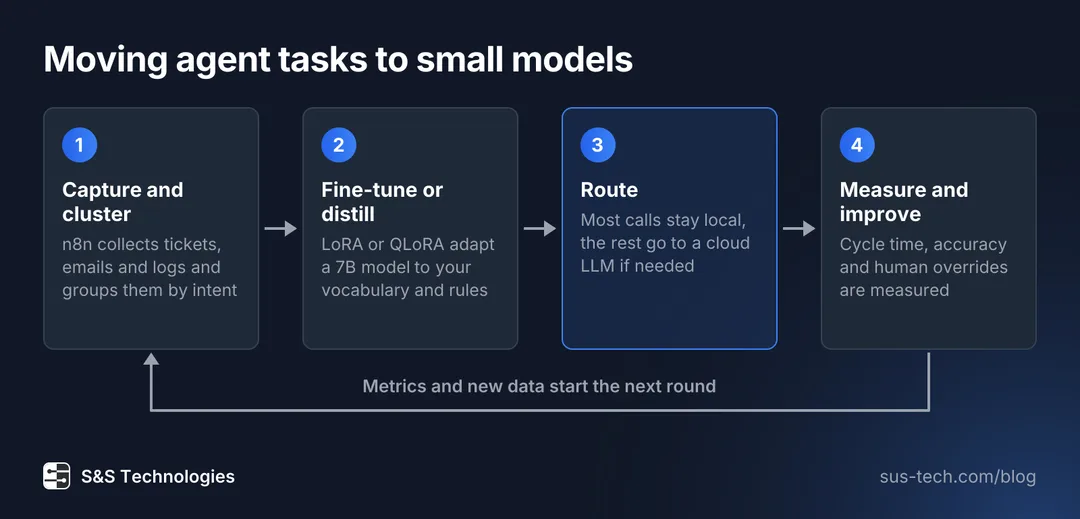
Clustering shows which tasks come up often enough to be worth a small model. Fine-tuning with LoRA or QLoRA adapts a 7B model to them, the router sends the matching calls to it and the measurements of cycle time, accuracy and human overrides show where it still falls short. Those results and new tickets start the next round.
What small models change
- Faster ticket resolution thanks to fast local inference and on-prem AI.
- Lower monthly inference spend at high volumes, hardware included (see our cost comparison).
- Fewer manual touches on repetitive ERP entries, freeing staff for exception handling and analysis.
- GDPR-compliant data residency with audit-ready logs.
- Reduced vendor lock-in: swap or retrain models without renegotiating API contracts.
Example use cases
- Invoices in ERP System: An SLM classifies supplier invoices, extracts payment terms and triggers automated approval flows that write back to ERP.
- Real-time ITSM enrichment: During incident intake, the model queries CMDBs and past tickets, then appends probable root-cause fields before the first human sees it.
- Automated HR inbox: A multilingual 7B model drafts replies to routine leave requests, escalating only policy exceptions.
- Sales-ops quote builder: The SLM assembles configurable quotes from ERP price lists, trimming response times during peak season.
Running a first pilot
- Run a focused pilot: Choose one high-volume, low-risk agent task and map it to an SLM.
- Apply the conversion algorithm: Our SLM-migration playbook turns the NVIDIA methodology into a working n8n recipe.
- Quantify ROI: Use process-mining dashboards to track cycle-time reduction and cost per ticket, then expand in quarterly increments.
- Scale safely: Extend coverage incrementally, adding rollback rules, shadow-testing and human-review nodes as confidence grows.
Ready to put small language models to work? Contact our team for a proof-of-value workshop.