
LLM Finetuning: LoRA and QLoRA

Fine-tuning large language models (LLMs) has become essential for organizations needing precise output in areas like legal, finance or internal support. But how can you achieve high-quality customization without burning through GPU hours or engineering budgets?
Why full fine-tuning is expensive
Full-parameter fine-tuning of LLMs sounds powerful - until you try it. Updating every weight in a 7B or 13B model means adjusting billions of values per training epoch. GPU memory needs grow quickly, experiments take a long time and even minor improvements start to feel costly.
For organisations in regulated or knowledge-heavy industries, delays in customizing models mean:
- Loss of competitive edge in automation and AI.
- Inability to comply with internal or industry-specific regulations.
- More pressure on internal IT teams to manage manual, error-prone processes.
As outlined in our RAG vs. Finetuning: Choosing the Right Strategy for your LLMs, Retrieval-Augmented Generation addresses some needs. But when your use case demands that the model knows your domain natively - not just when prompted - then fine-tuning becomes essential.
Fine-tuning with LoRA and QLoRA
At S&S Technologies, we offer pragmatic, cost-efficient fine-tuning of LLMs using LoRA (Low-Rank Adaptation) and its extension, QLoRA. These methods greatly reduce the compute required to adapt a foundation model to your data - be it legal terminology, financial document patterns or internal support FAQs.
Whether you're building an internal knowledge bot, an AI-powered compliance checker or a language-aware ERP assistant, our team fine-tunes LLMs to understand and speak your business language. Unlike traditional approaches, our implementations are:
- Cost-optimized with GPU-efficient tuning
- Fully integrated into platforms like n8n
- Aligned to your ITSM, ERP or document governance requirements
We combine tuned models with proven infrastructure like ITSM plugins, RAG pipelines and Git-based workflow governance.
How LoRA and QLoRA work
The three approaches differ in which weights are trained and in how the base model is stored:
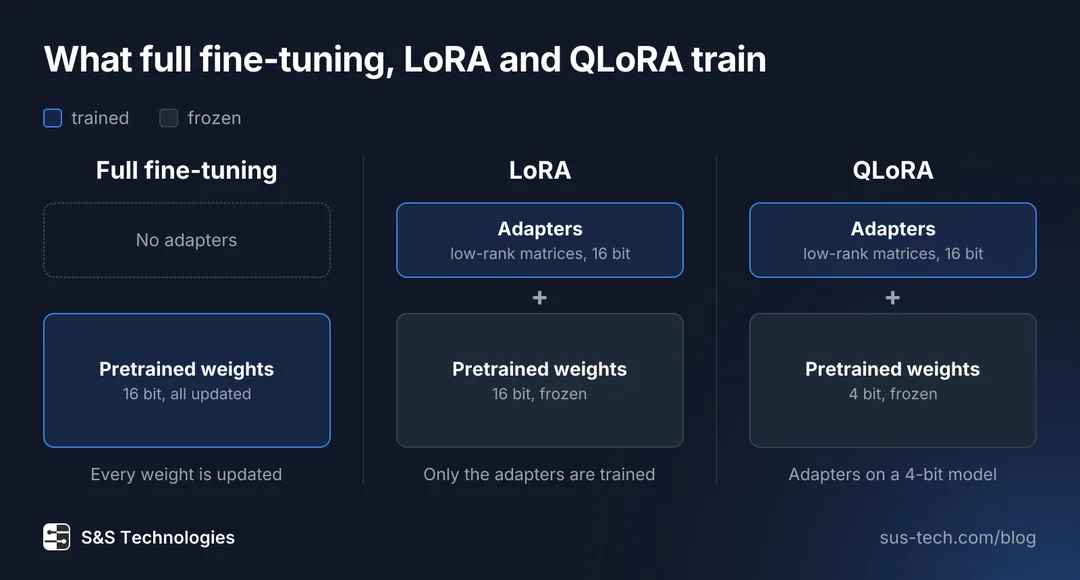
Full fine-tuning updates every weight of the model. LoRA keeps the pretrained weights frozen and trains only small low-rank matrices, the adapters. QLoRA trains the same kind of adapters while the frozen base model is stored in 4 bit.
Here's how LoRA and QLoRA make it all possible:
LoRA (Low-Rank Adaptation)
LoRA targets efficiency by modifying just a slice of the weight-space:
- Small changes only: It preserves the pretrained model and trains only small, low-rank matrices to capture the adapted behavior.
- Memory savings: For GPT-3 with 175 billion parameters, the LoRA paper reports 10 000 times fewer trainable parameters and a third of the GPU memory compared with full fine-tuning (Hu et al., 2021). How large an adapter is depends on the rank and on how many weight matrices get one.
- Adjustable rank: Depending on the complexity of your domain, we set LoRA's rank between 8 and 256. For GPT-3 the LoRA paper found that a rank of one or two can be enough, while a higher rank brings LoRA closer to full fine-tuning.
QLoRA (Quantized LoRA)
QLoRA builds on LoRA by reducing precision during training:
- 4-bit quantization greatly reduces the memory the model weights need.
- Same quality: The QLoRA paper fine-tuned a 65-billion-parameter model on a single 48 GB GPU and matched the results of 16-bit fine-tuning (Dettmers et al., 2023). Whenever a weight is used, it is converted back to 16 bit for the computation.
- Full-layer adaptation: The same paper shows that adapters on all linear layers of the transformer are needed to reach the quality of full fine-tuning.
Platform integration
We embed fine-tuned models into existing business workflows:
- Integrated with n8n flows that watch S3 buckets, ERP exports or compliance docs.
- Connected to ITSM UIs and ERP help panels.
- Governed with role-based access and audit trails - just like in our Internal Knowledge Bases with RAG.
What efficient fine-tuning brings
With LoRA and QLoRA, companies get:
- Much lower compute and cloud costs for the adaptation than full fine-tuning, as the figures of the LoRA paper above show.
- Faster deployment cycles, thanks to smaller, modular parameter changes.
- Improved domain specificity, so the model answers in the context of your domain.
- Answers that are easier to check: a model tuned on your examples follows your format and terms.
Both papers report how much GPU memory the training needs with and without adapters:
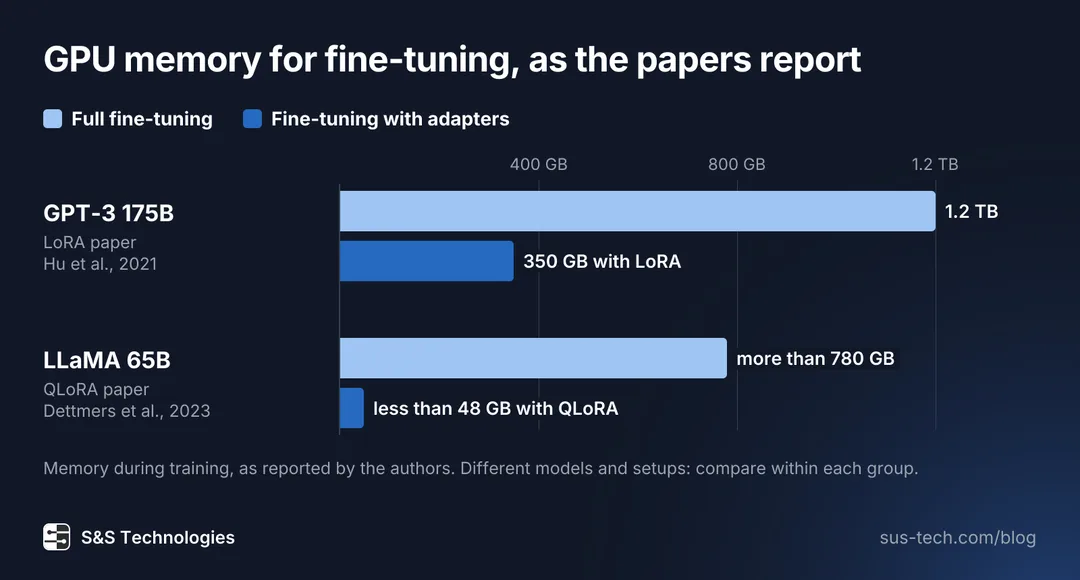
On GPT-3 with 175 billion parameters, LoRA cut the GPU memory needed for training from 1.2 TB to 350 GB (Hu et al., 2021). For LLaMA 65B, 16-bit full fine-tuning needs more than 780 GB of GPU memory and QLoRA less than 48 GB (Dettmers et al., 2023). The two papers measured different models, so the figures show the size of the savings rather than a direct comparison of LoRA and QLoRA.
When combined with internal data pipelines, businesses can automate support or onboarding tasks at scale - just like clients using our n8n workflows with small language models.
How a fine-tuning project runs
Ready to fine-tune a model for your domain using LoRA or QLoRA? Here's how we typically proceed:
- Discovery call: Clarify your goals, data environment and candidate workflows.
- Dataset prep: Securely gather and structure your domain content.
- Model selection and tuning: Choose a base model and apply LoRA or QLoRA adapters.
- Workflow integration: Insert the tuned model into your n8n, ERP or ITSM systems.
- Govern and monitor: Track performance and maintain update flexibility.
Contact our team at office@sus-tech.at to explore how S&S Technologies can customize an LLM for your use case - and deliver results using efficient, governed automation. Automate. Optimize. Scale.