
RAG vs. Finetuning: Choosing the Right Strategy for your LLMs

When should you train your AI model - and when should you simply teach it to fetch the right information? As large language models (LLMs) power enterprise applications across Austria and beyond, CIOs and service operations leaders must understand the difference between Retrieval-Augmented Generation (RAG) and fine-tuning. Your choice affects performance, compliance, customer trust and ROI.
Two ways to adapt a language model
Many companies face the same question: how to adapt LLMs to their business context. Data is often proprietary, regulated or in continuous flux. Misapplying enhancement techniques can lead to inaccurate outputs, rising costs or unsustainable infrastructure.
For example, using a static fine-tuned model to answer dynamic product queries - or a generic chatbot in a legally regulated industry - can result in:
- Poor accuracy due to outdated training data
- Expensive inference caused by long context prompts
- Lack of governance and source traceability
As explained in Internal Knowledge Bases with RAG: Architecture, Tools and Maintenance, technical leaders must consider how often the business's knowledge base changes, the domains the chatbot must operate in and trust requirements like GDPR.
Choosing RAG, fine-tuning or both
At S&S Technologies, we help businesses in Austria and across the EU choose the right method - or blend - of RAG and fine-tuning to match their needs. Our team evaluates:
- Data Volatility: Is your knowledge changing daily, monthly or fairly stable?
- Inference Trust: Do answers need verifiable sources or can they rely on general behaviour?
- Domain Adaptation: Does your field (finance, legal, insurance) require precise formatting or tone?
We combine this advice with hands-on implementation and our experience in workflow automation, governed automation and AI agent orchestration. Our solutions integrate with ERP platforms, ITSM tools and secure EU-based infrastructure.
Automate. Optimize. Scale.
How we implement RAG and fine-tuning
We implement both strategies and often combine them.
The two methods put your knowledge in different places:
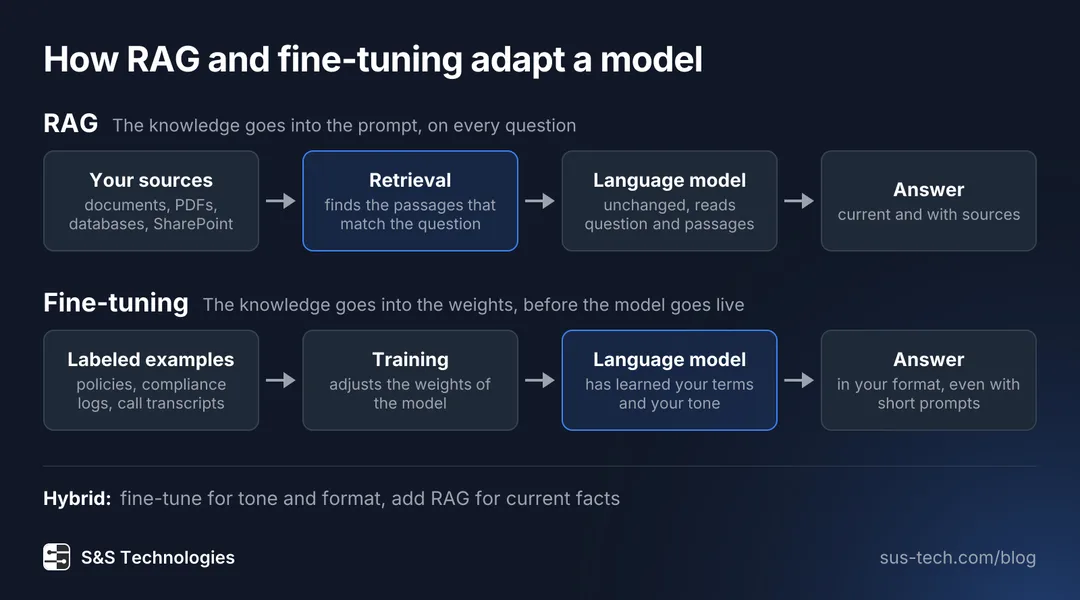
RAG leaves the model unchanged and adds the passages that match each question to the prompt, so answers stay current and name their sources. Fine-tuning trains the model on labeled examples before it goes live, so the knowledge sits in the weights and prompts stay short. A hybrid setup fine-tunes for tone and format and adds RAG for current facts.
Retrieval-Augmented Generation (RAG):
- Connect your internal documents, SQL databases, PDFs or SharePoint resources to a retriever pipeline using n8n and encrypted vector stores
- When a user submits a query, the system retrieves the most relevant context from your corpus and adds it to the LLM prompt
- This keeps the model output current, reduces hallucinations and enables source traceability
Fine-tuning:
- Use labeled, domain-specific datasets (e.g. policy documents, safety compliance logs, call transcripts)
- We update the model's weights so it intrinsically understands your language, workflows and expected tone
- Enables faster responses, lower compute cost and tighter alignment with industry norms
Hybrid Approach:
- Combine both methods for complex apps
- For example, fine-tune a model for legal writing tone - but use RAG to inject current case law or policy updates
- Secure deployment in EU data centers or on-prem edge nodes to stay GDPR-compliant (read more)
What the right choice brings
Choosing the right enhancement strategy brings clear benefits:
- RAG pipelines reduce hallucinations because answers rest on retrieved sources, which matters most in regulated sectors
- Fine-tuned models need shorter prompts, which cuts inference time and compute costs
- More transparency builds customer trust - critical in finance and insurance sectors
- Aligns tone, terminology and domain knowledge for better UX and compliance
- Supported by tools such as n8n and full logging for the records of processing under Article 30 GDPR
With our governed automation frameworks, all enhancements run within a secure and observable architecture.
How to decide for your use case
Here's how to decide what's right for your use case:
- Inventory your data. Is it structured or unstructured? Static or changing?
- Define your use case. Chatbots, document summarisation, form automation?
- Evaluate trust needs. Do users need citations and source transparency?
- Assess infrastructure. Can you host models on-prem or in EU data centers?
- Mix if needed. Fine-tune tone and behaviour; RAG for freshness and clarity
The guide below sums up which needs point to which method:
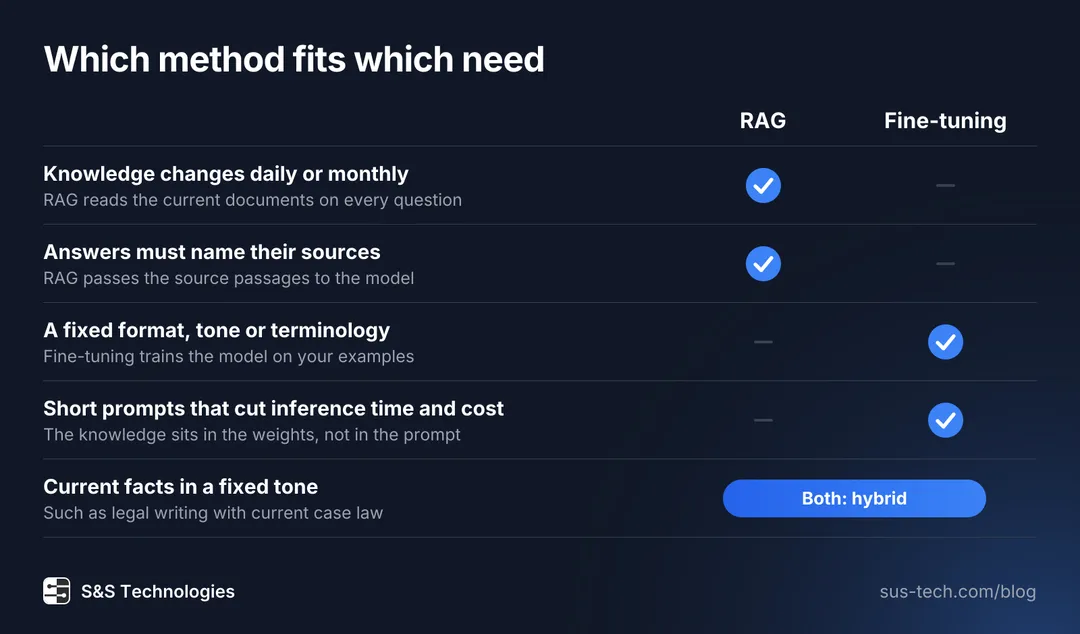
Knowledge that changes daily or monthly and answers that must name their sources point to RAG. A fixed format, tone or terminology and short prompts point to fine-tuning. Where a use case needs current facts in a fixed tone, such as legal writing with current case law, the two are combined.
Ready to build scalable, accurate and compliant AI workflows? Contact our team at office@sus-tech.at to get started.